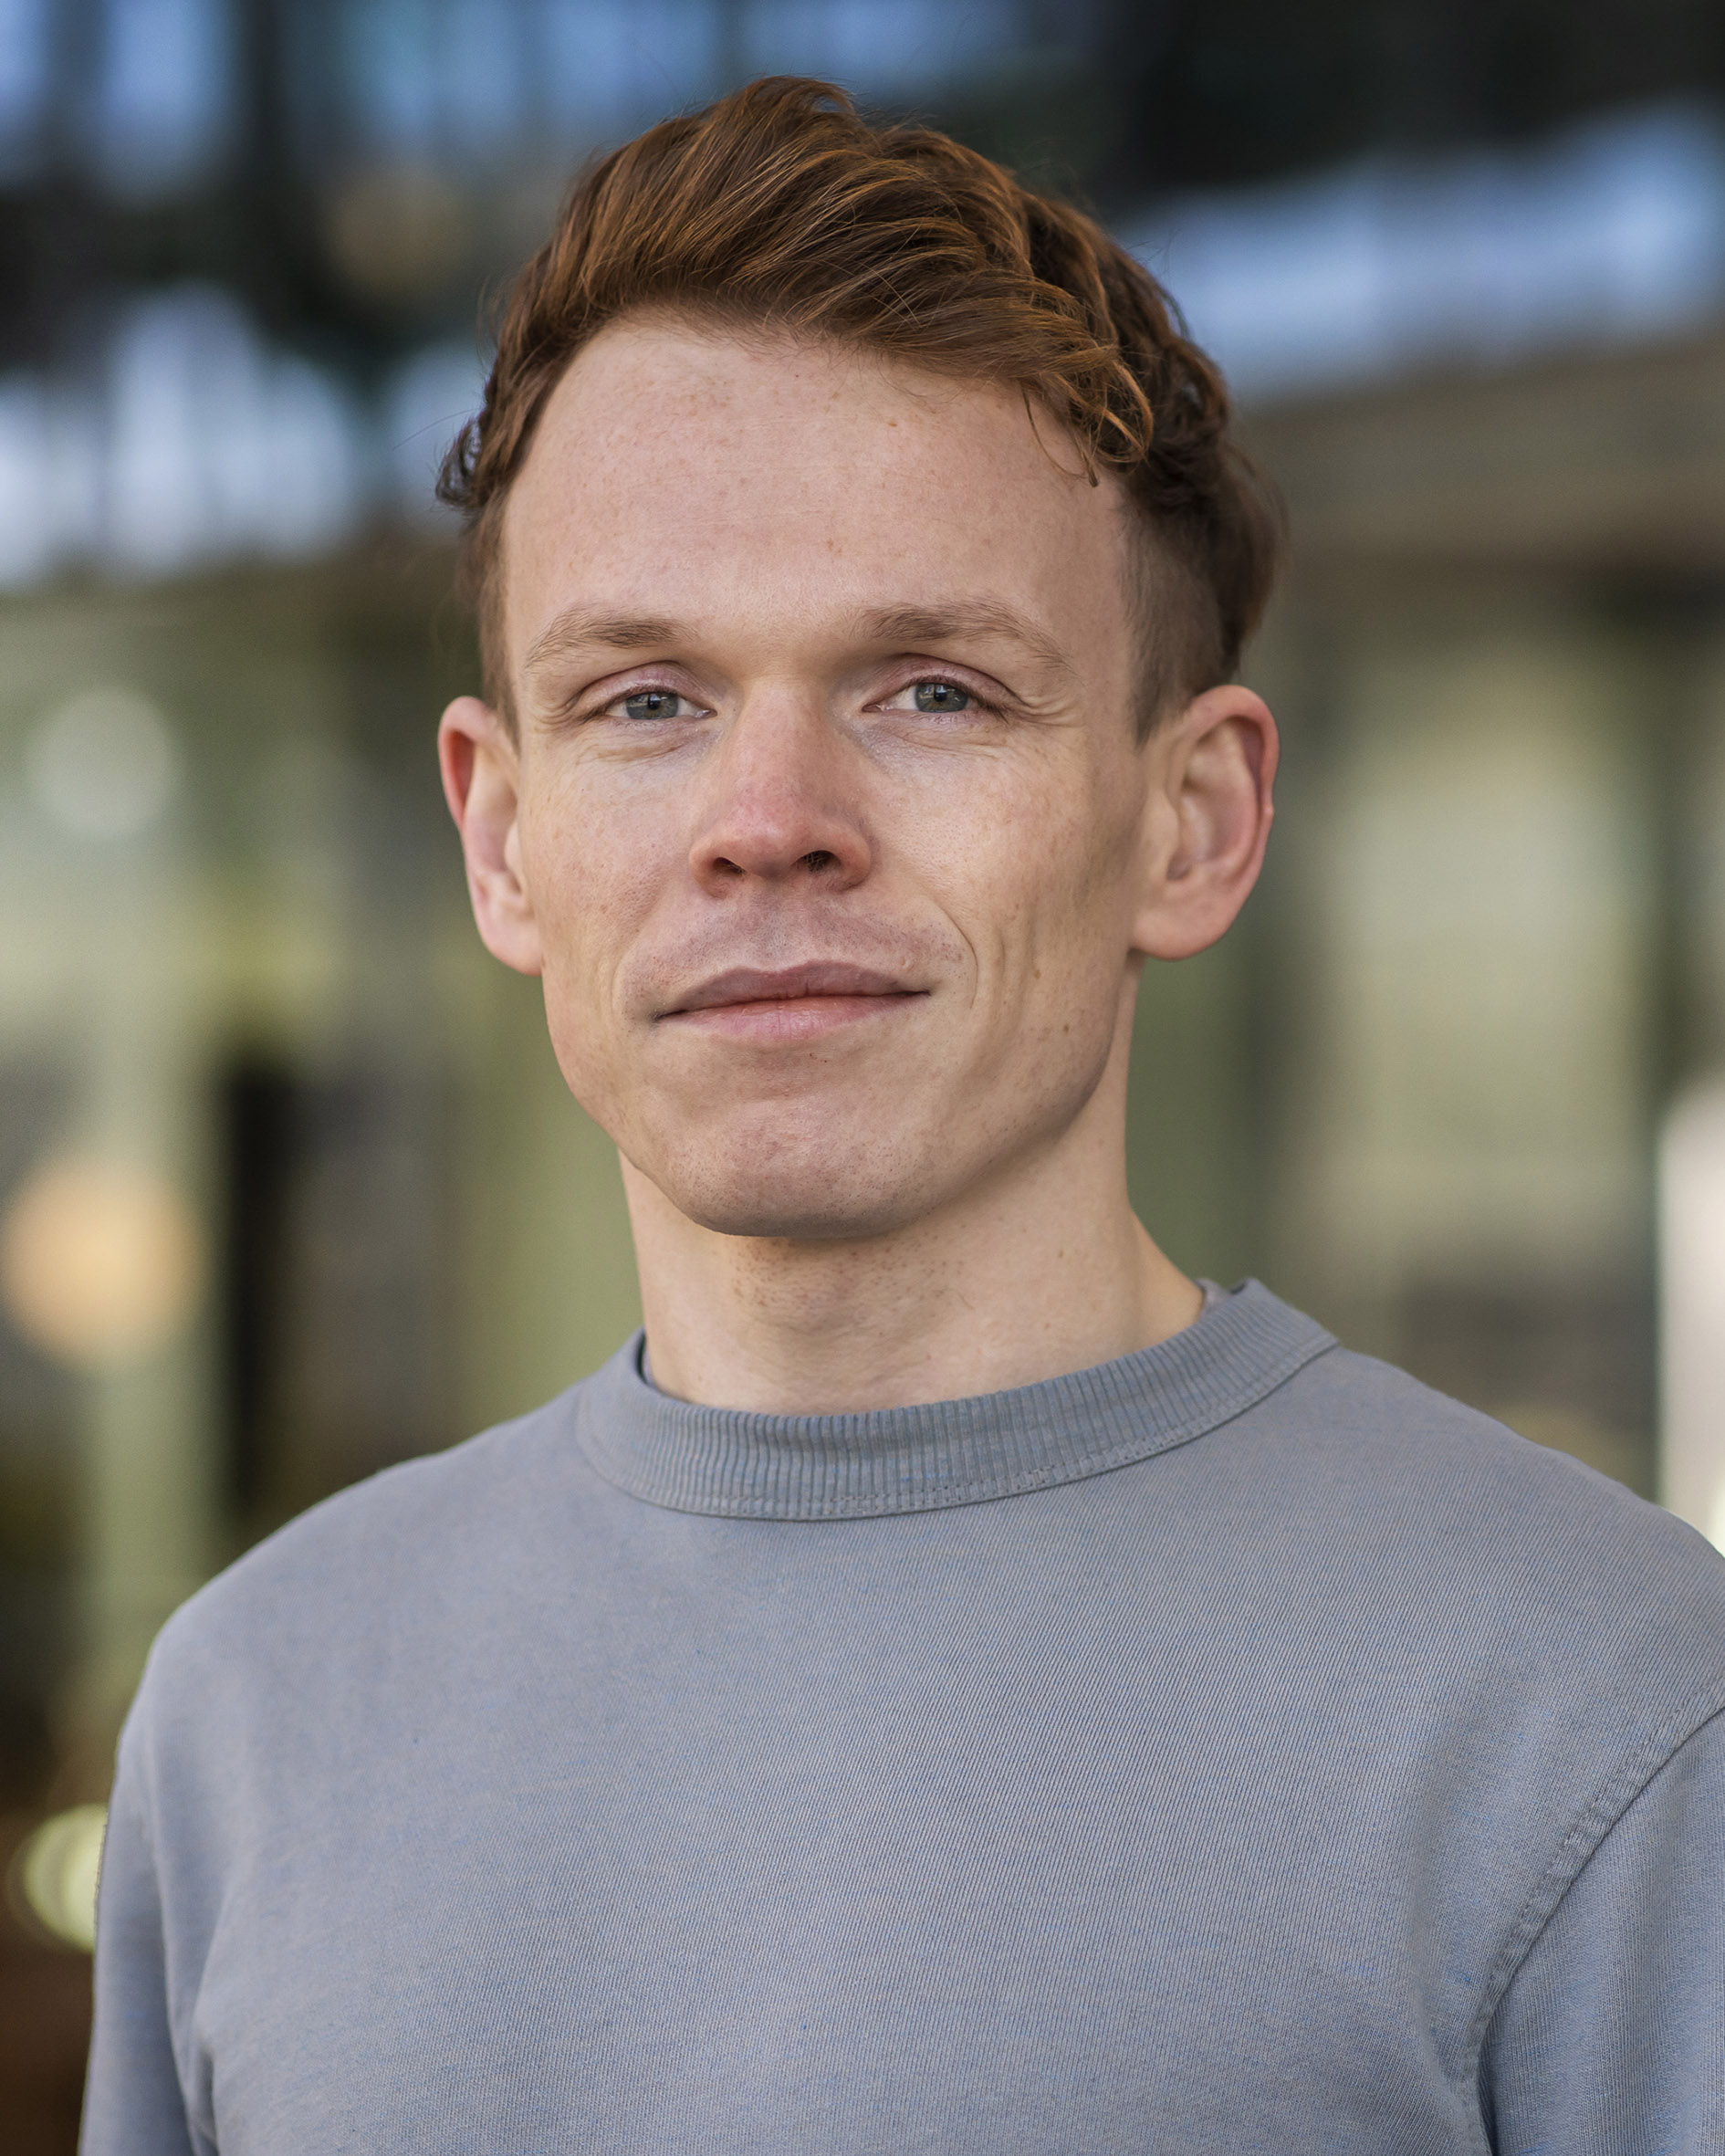
Jesse van Remmerden
I am a fourth-year PhD candidate in the Information Systems group at Eindhoven University of Technology (TU/e), supervised by Zaharah Bukhsh and Yingqian Zhang. My research lies at the intersection of combinatorial optimization and machine learning: I build systems that plan and schedule — for factory floors, vehicle fleets and civil infrastructure — using reinforcement learning, discrete diffusion models and language models.
A single question runs through this work: what can learned planners do without a simulator, without expert demonstrations, and without a hand-specified objective? The prevailing answer has been “not much.” Deep reinforcement learning for scheduling has conventionally required millions of interactions with a hand-built simulator, and neural routing solvers have required the objective to be expressible as a scalar to minimise. My results show that neither constraint is fundamental.
Research
Learning to schedule without a simulator
Job shop scheduling assigns factory operations to machines so that production finishes as early as possible. Deep RL methods for this problem learn by trial and error inside a simulator — but for realistic production environments such simulators are expensive to build and often simply do not exist.
Offline-LD (Machine Learning, 2025) was the first fully end-to-end offline RL approach for the Job Shop Scheduling Problem, learning dispatching policies purely from a fixed set of past schedules. It introduces maskable variants of Quantile Regression DQN and discrete Soft Actor–Critic trained with Conservative Q-Learning, together with a novel entropy bonus for maskable action spaces and a reward normalisation scheme for the offline setting. Trained on only 100 solutions from a constraint programming solver, it matches or outperforms online RL baselines that require millions of simulated interactions. Adding noise to the expert dataset yields comparable or better results — a useful property, since real industrial logs are inherently imperfect.
CDQAC (TMLR, 2026; project page) pushes the premise considerably further. Conservative Discrete Quantile Actor–Critic couples a quantile-based critic with a delayed policy update to estimate the full return distribution of each machine–operation pair. It matches or beats state-of-the-art simulator-trained methods across four standard benchmark suites, generalises to instances with ten times as many jobs as seen during training, and needs just 10–25 training instances. Most counter-intuitively, CDQAC performs best when trained on schedules produced by a random heuristic, outperforming training on higher-quality genetic-algorithm and priority-dispatch-rule data.
That result is not an anomaly but a measurable principle. I showed that what governs offline performance is how much of the decision space the training data covers, not how good the demonstrated solutions are — a rank correlation of −0.95 between data quality and resulting policy quality. This gives a practical and transferable rule for constructing datasets for learned decision-making systems: optimise for coverage, not for optimality.
Routing from instructions written in plain English
Neural routing solvers can plan an efficient tour, but they cannot accommodate a request such as “visit customer 7 before customer 4” or “keep these three stops on one truck” — the kind of constraint a dispatcher expresses dozens of times a day. DROVER (under review) addresses this gap with language-conditioned discrete diffusion.
I built the first benchmark for this setting: 26+ request types, approximately 3 × 10⁹ possible phrasings, reference solutions from established solvers, and an automatic verifier that decides whether a proposed tour actually obeys the stated request. The model reads the request through a frozen language model and steers its denoising trajectory toward satisfying it using a new guidance technique.
DROVER satisfies the stated request in 98–99% of cases on instances from 50 to 1,000 stops, against roughly 32% for the strongest existing neural solvers. On request types never encountered during training it reaches 87–90%, where existing solvers achieve 0%. Given no request at all, it remains competitive with the best neural solvers on plain tour length, and is the best of them at 100 stops.
Multi-objective maintenance planning for real infrastructure
Amsterdam’s historic quay walls are deteriorating, and the city must decide which to repair and when, over a fifty-year horizon, balancing cost against the probability of collapse. Conventional RL approaches collapse such objectives into a single reward through reward shaping, which quietly discards the trade-off that asset managers actually need to reason about.
MO-DCMAC (Neural Computing and Applications, 2025) optimises directly over multiple objectives even when the utility function is non-linear. Rather than inventing a proxy reward, I turned FMECA — the failure mode, effects and criticality analysis methodology that Amsterdam’s asset managers already use in practice — into the training objective, so the learned policy optimises the quantity practitioners genuinely care about. MO-DCMAC produced the best maintenance plan in 5 of 6 test settings, improving on the rule-based strategies currently in use by up to 46%, and is the first deep multi-objective RL method of its kind applied to a real-world infrastructure problem.
This work is part of STABILITY (Sustainable Circular Life Extension Strategies for Inner-City Bridges and Quay Walls, NWA.1431.20.004), a 2023–2027 Dutch Research Agenda consortium funded by NWO and the City of Amsterdam.
How I work
In each of these projects I built the training data, the automatic verifier that decides whether a solution is correct, and the benchmark itself — and then released all of it. Reproducibility is not an afterthought here: evaluating learned optimisation methods is notoriously sensitive to instance generation and baseline tuning, and a result that cannot be independently reproduced is not yet a result. All implementations are publicly available on GitHub, with datasets and pretrained checkpoints on Hugging Face.
I also work on human-in-the-loop decision making. At IJCAI-ECAI 2026 in Bremen I co-presented a half-day tutorial on Deep Reinforcement Learning for Combinatorial Optimization and presented DROVER at the Data Science Meets Optimisation workshop.
Contact
I am completing my PhD in January 2027 and am interested in postdoctoral and research positions.
Email: j.v.remmerden@tue.nl · jessevanremmerden@gmail.com
Office: Atlas 5.408, Eindhoven University of Technology